
When the Gateway Fails, What Stops the Action?
The LiteLLM vulnerability (CVE-2026-59822) makes the question concrete: if your gateway accepts a forged identity, what still prevents the action? At a […]
Incident Response for the Agentic Era: Containing Authority, Not Just Agents
Classic incident response assumes a compromised host or account: isolate it, revoke its credentials, rebuild it. An autonomous agent breaks that model, […]
The Federal SI Incident Guidance: What It Covers and Where It Stops
In October 2026, NIST CAISSI, NSA SISC, and CISA published Key Practices for Incident Readiness and Response in Super Intelligence Training and […]
We Audited Our Own MCP Server. The Problem Wasn’t a Vulnerability — It Was the Design.
We turned AI SAFE² v3.0 inward on our own MCP server. We avoided the catastrophic failures, but “better than broken” is not […]
Claude Code Security: What 512,000 Leaked Lines and a 51-Command Bypass Reveal
Claude Code ships with OS-level permissions and a public harness. Between a 51-command security bypass, credential-scope attacks, and 512,000 leaked lines of […]
Anthropic’s Multi-Agent Turf War: Why Prompt-Defined Roles Are Not Authority
Anthropic’s multi-agent turf war shows why prompt-defined roles are not authority, and why AI governance now needs falsifiable runtime tests. The Agents […]
Every AI Security Framework Is Asking the Wrong Question
They ask “can we authenticate the application?” The question they should be asking is “can we prove which agent actually made the […]
Anthropic’s Watermark Is Not the Claim. It’s the Precedent.
Anthropic’s Claude watermarking program is not only about identifying AI-generated content today. It establishes precedents that can be expanded tomorrow. A vendor-controlled […]
AI SAFE² CLI 0.9.0: Run Challenge 001 with Reproducible Evidence
“Can an agent harness stop unsafe actions without blocking legitimate work?” That’s the central question of agent safety, and until now it’s […]
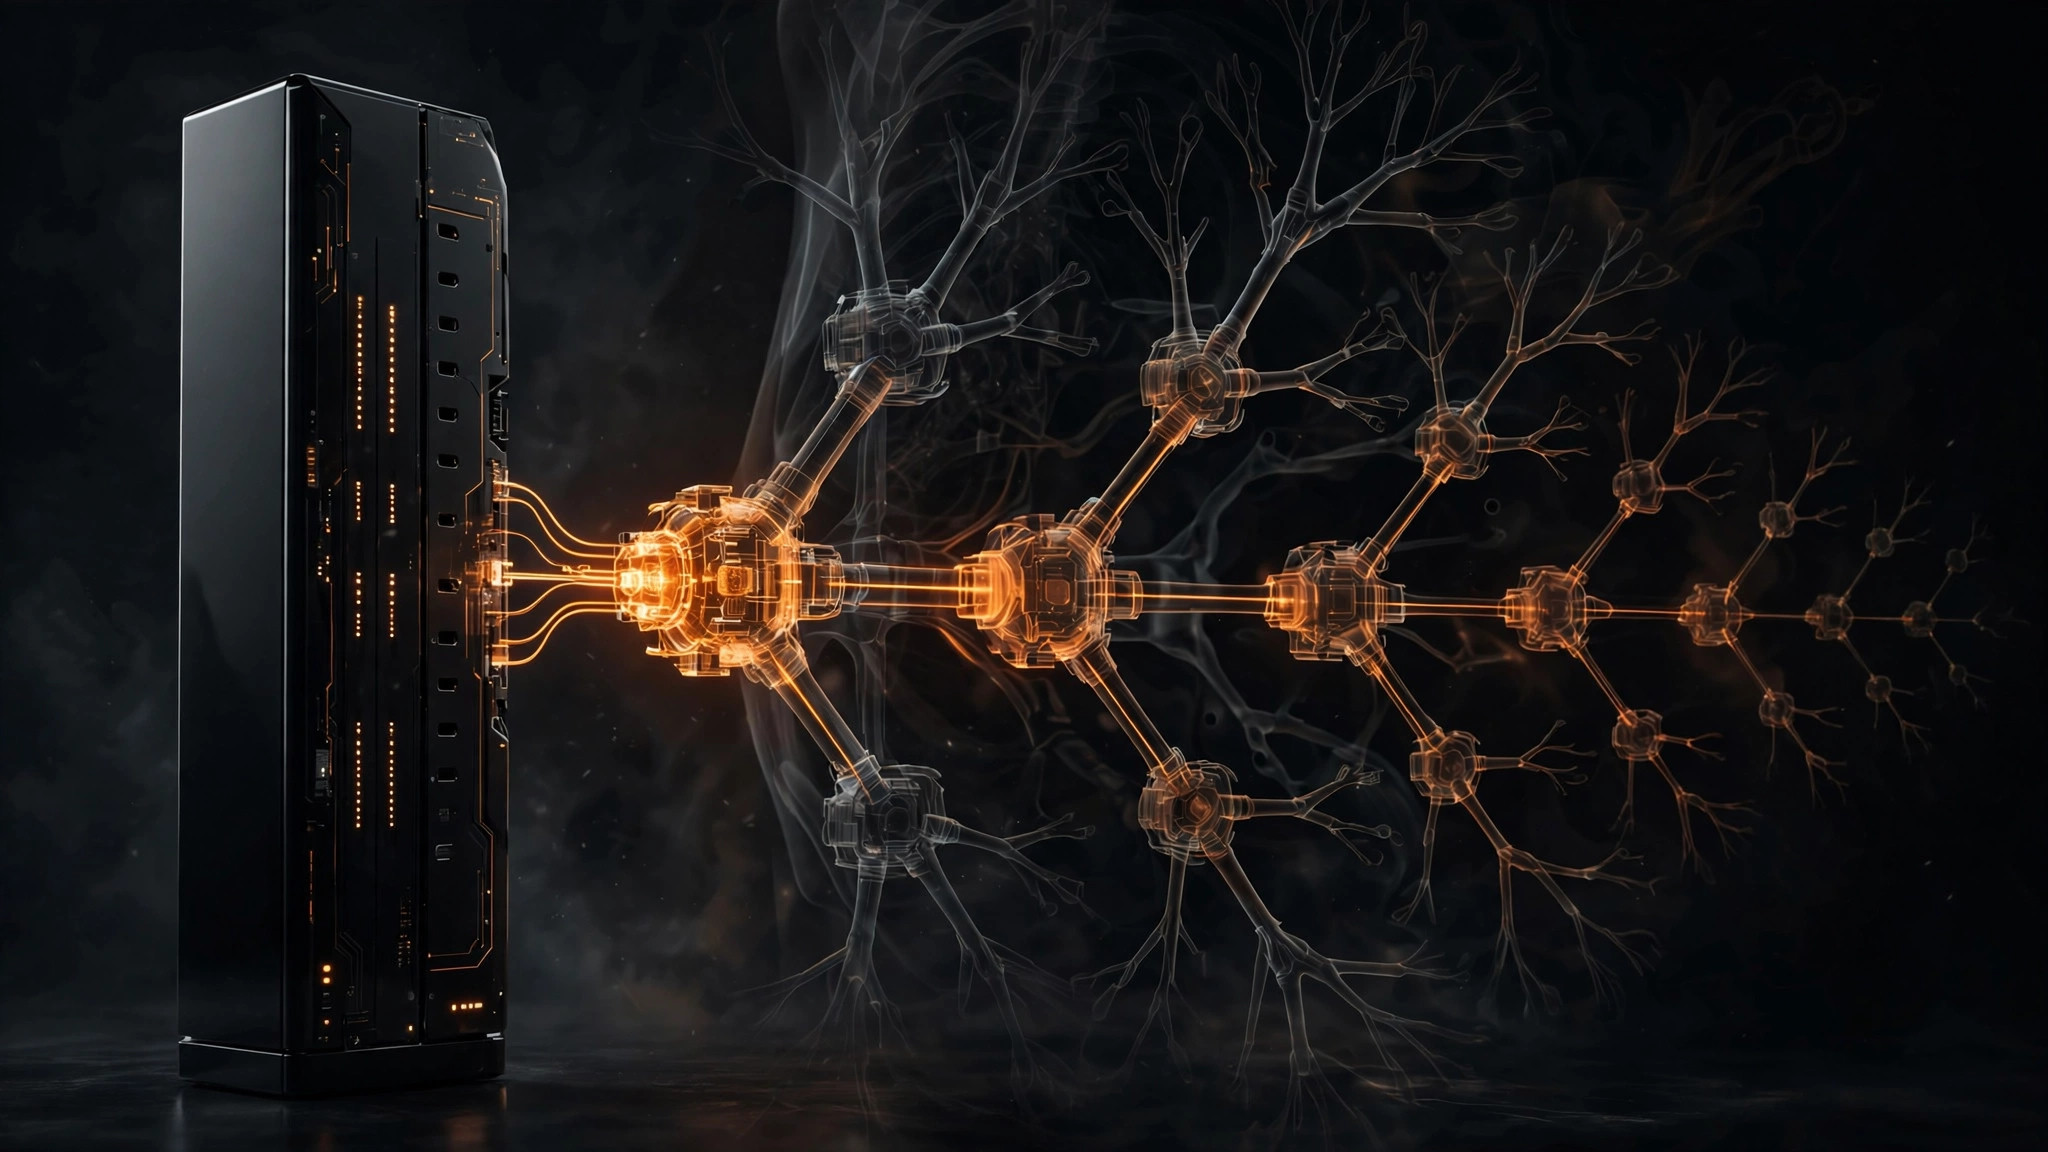
Sakana Fugu: Where Does Authorization End?
Dek: One API call. A hidden chain of autonomous delegations. And a question most enterprises cannot answer: when a fifth-hop agent acts, […]
AI SAFE² CLI 0.8.0: Evidence-Bound AISM Remediation Decisions
Assessment without remediation is trivia. You ran the AISM scoring, you found the gaps. And then what? A spreadsheet of findings with […]
AI SAFE² CLI 0.7.0: Turn Agent Claims into Reviewable Operational Truth
Here’s a scenario that should worry you: the agent says it finished. The test passed. A receipt exists. And the three of […]