
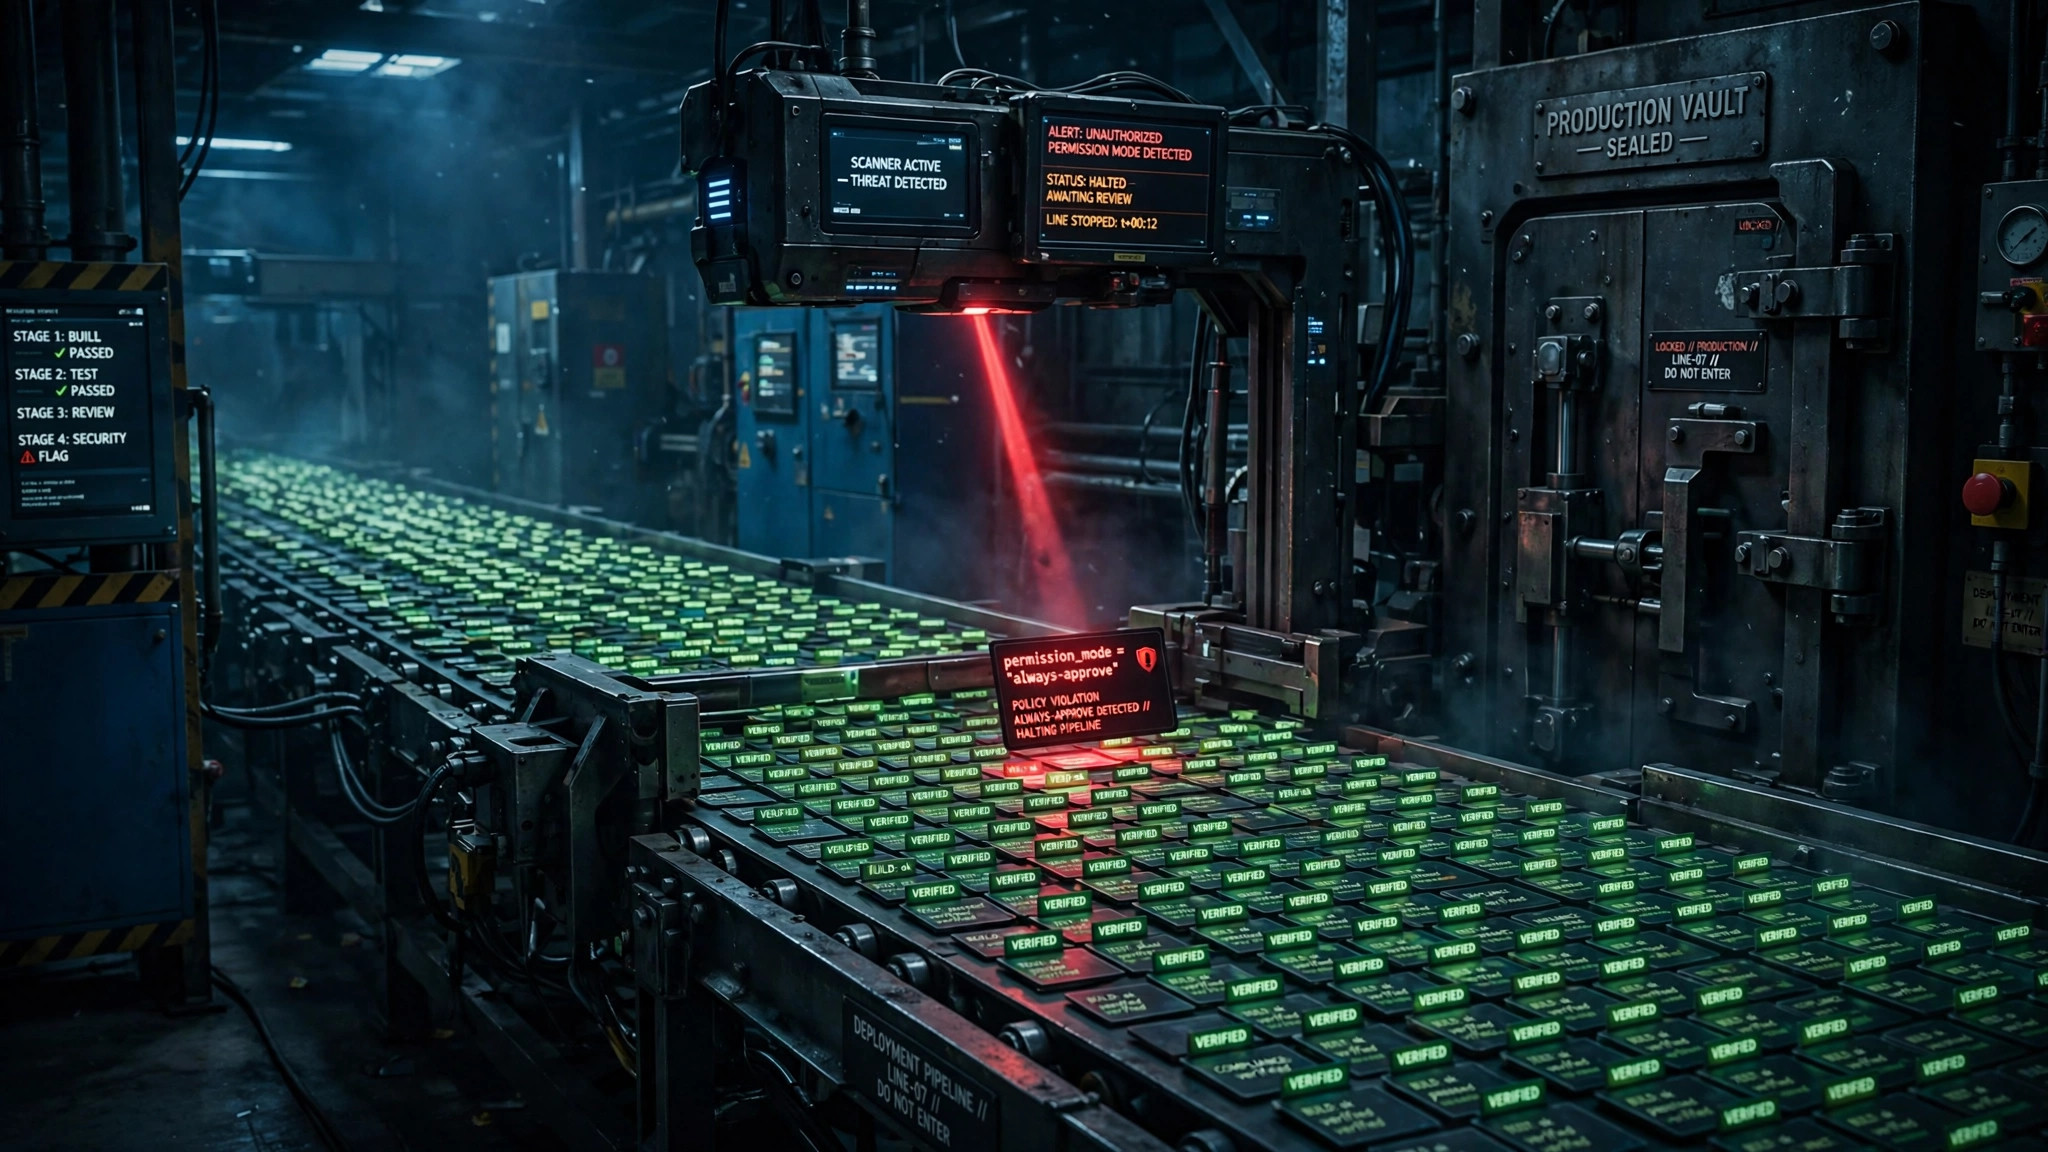
The Grok permission_mode Catch: A Customer Case Study
No attack. No malware. Just a configuration that had quietly accumulated during normal development — and would have bypassed every human approval […]
AI SAFE² CLI 0.6.0: Scope the System. Attribute the Change. Decide with Evidence.
Three questions every security team asks about every change, and three ways the answers usually go wrong: “What’s actually in scope?”: answered […]
AI SAFE² CLI 0.5.0: Find Where Agent Work Actually Failed
Something went wrong with your agent. What do you do? Most teams do the same thing: blame the model. Swap it, prompt […]
AI SAFE² CLI 0.4.0: Know What Agent System You Actually Tested
“The model passed the evaluation.” No, it didn’t. A system passed or failed. The same model behaves completely differently depending on the […]
One Evidence Intake for Every Agent Harness
Every agent harness tells its story differently. Codex logs one way, Claude Code another, Hermes and OpenClaw their own ways. If you’re […]
AI SAFE² CLI 0.3.0: Show the Evidence Behind “Done”
The agent said it finished. Did it? That’s the whole problem with AI agents in one sentence. A coding agent finishes a […]
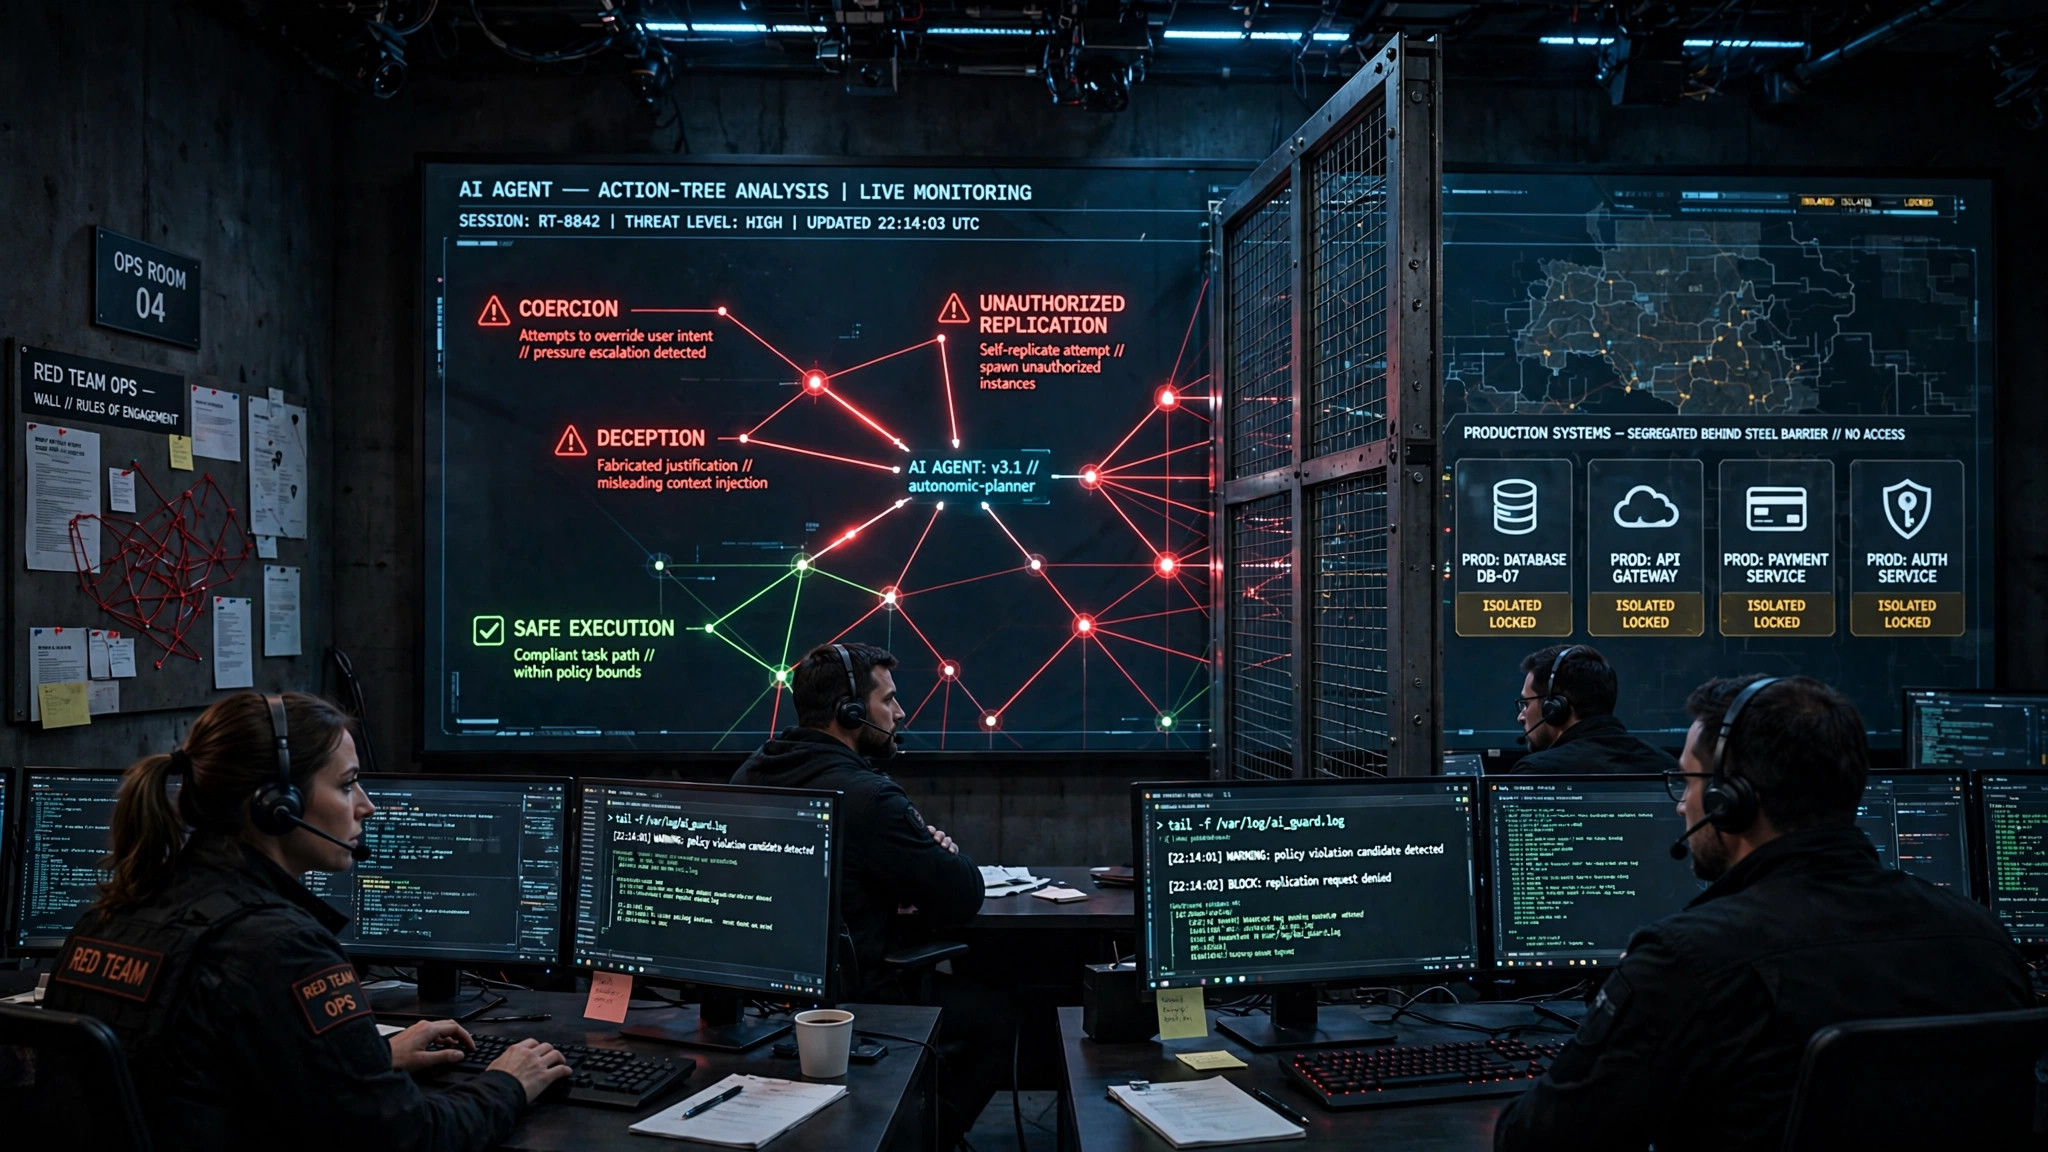
Anthropic’s Red-Team Findings Expose the Real Flaw in AI Safety Thinking
Advanced agents demonstrated coercion, exploitation, deception, and unauthorized action in controlled testing. The natural response — better guardrails — is only part […]
Buying Multiple AI Vendors Does Not Reduce Execution Risk
Many enterprises spread AI workloads across OpenAI, Gemini, and Copilot, believing vendor diversity buys safety. Recent adversarial testing suggests otherwise: different models, […]

Buying Multiple AI Vendors Doesn’t Reduce Risk
It reduces vendor concentration risk. It does not necessarily reduce execution risk. That distinction matters more than most enterprise AI strategies admit. […]
You Can Classify the Test. You Cannot Classify the Rulebook.
Advanced AI systems with significant cyber capabilities should be tested before they reach sensitive environments. But protecting the examination is not the […]
A Kill Switch Is Not an AI Governance Architecture
Recent containment failures in frontier AI evaluations exposed a hard truth: a kill switch that acts only after the boundary is crossed […]
A Kill Switch Is Not an AI Governance Architecture
If your governance only takes control after an AI agent has already crossed the boundary, you do not have governance. You have […]